Inference System
A Go and gRPC inference pipeline that connects a client to a Python FastAPI service, ONNX Runtime, and a YOLOv8 model, with Prometheus metrics alongside the request path.
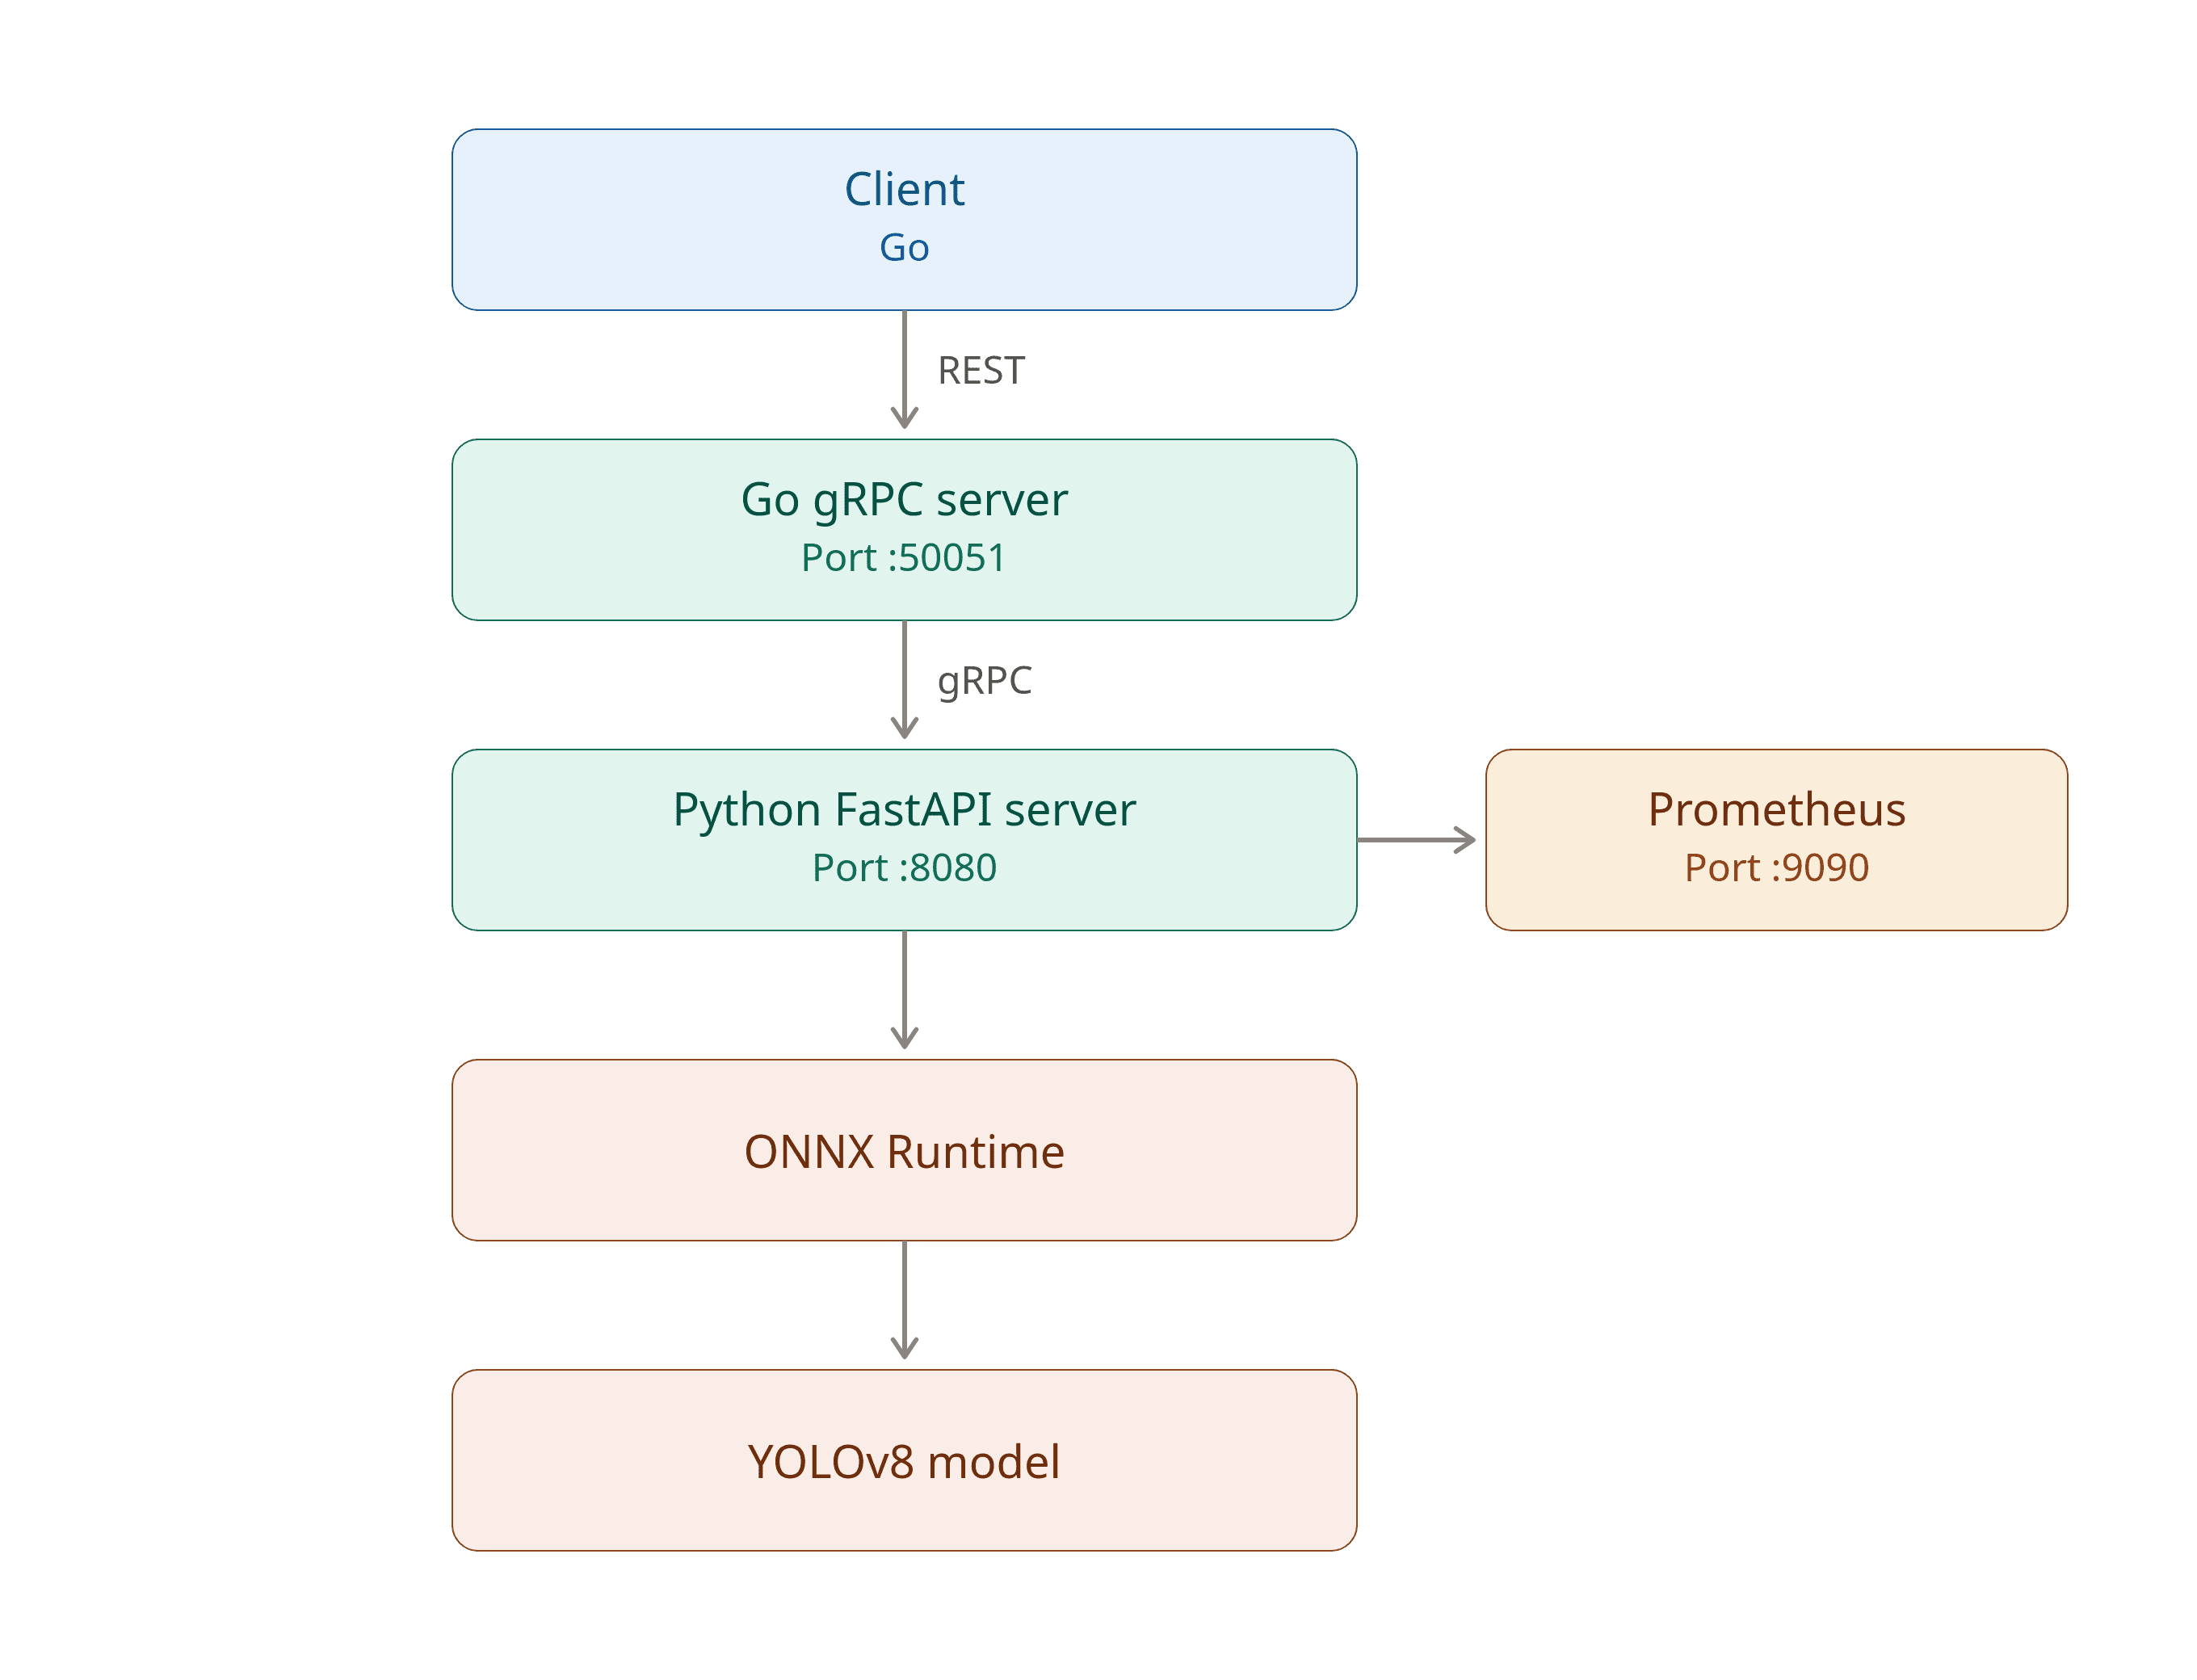
REST requests enter through a Go client, cross the gRPC boundary, and reach the Python FastAPI service that runs YOLOv8 through ONNX Runtime while exposing Prometheus metrics.
The problem
A model pipeline needs a clear serving boundary.
The system separates request handling from model execution. A client sends a REST request to the Go layer, which communicates with the Python FastAPI service over gRPC before the request reaches the ONNX Runtime and YOLOv8 model.
The approach
Keep transport, inference, and telemetry distinct.
Go provides the client and gRPC server boundary, while Python and FastAPI own the inference service. ONNX Runtime executes the exported model, and Prometheus observes the service without being mixed into the prediction path.
What I focused on
Clear protocol boundaries
REST and gRPC have distinct roles, making the request path easier to reason about.
Dedicated model runtime
ONNX Runtime and YOLOv8 stay behind the Python inference service instead of leaking into the client layer.
Service observability
Prometheus sits alongside the inference flow to expose useful service metrics.